Amazon's SP-API returns data in 47 formats across 20+ endpoints. Without normalization, analysis is impossible. Learn what normalized Amazon data looks like, why it matters, and how to get it without building everything yourself.
Amazon's SP-API returns data in 47 different formats across 20+ endpoints. Without normalization, you're drowning in inconsistent schemas, duplicate identifiers, and fee codes that mean different things in different reports. This guide explains what normalized Amazon data looks like and why it's the foundation for any serious analytics.
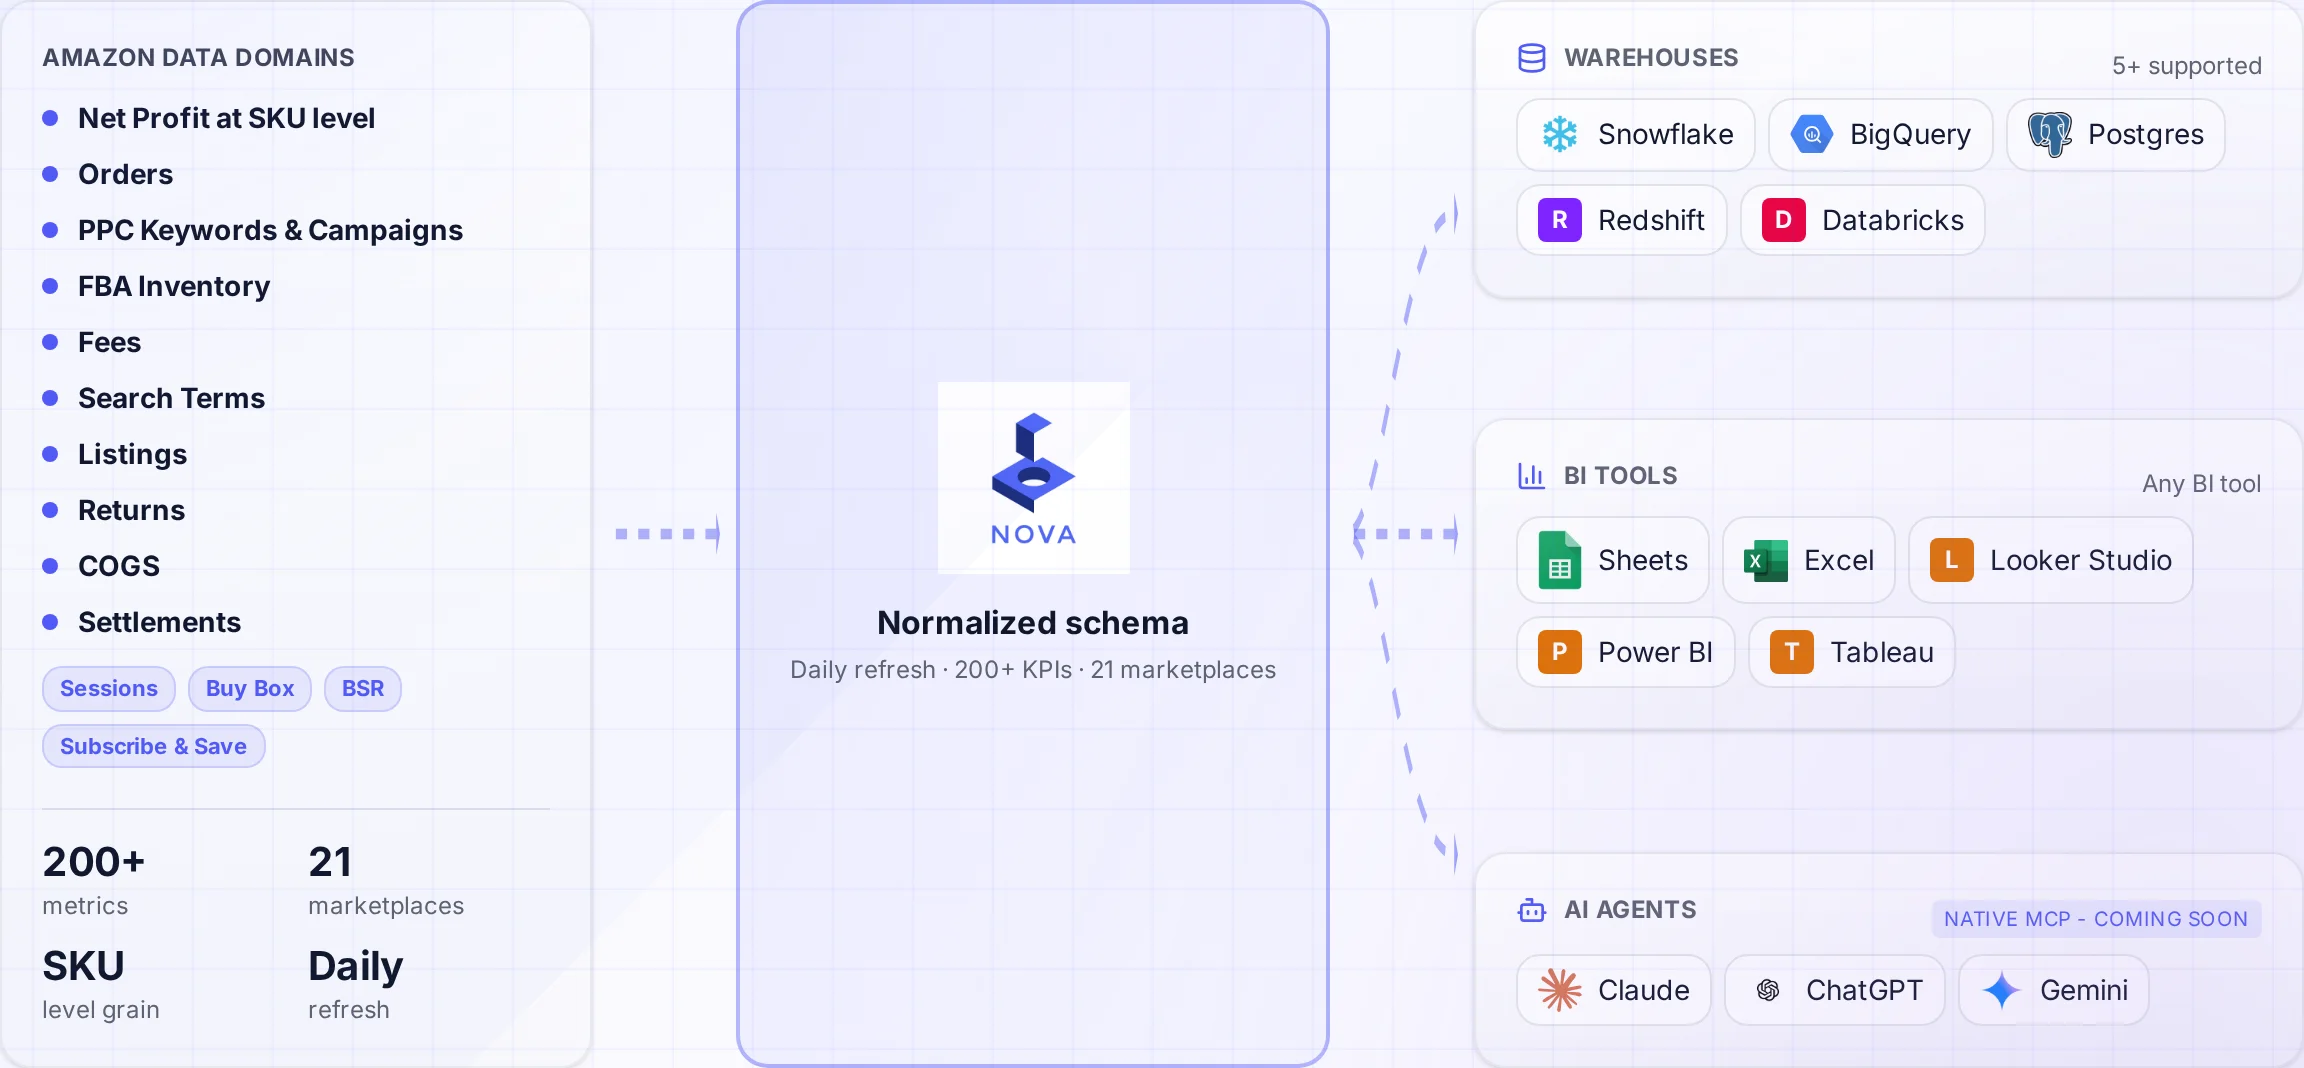
A normalized schema connects Amazon data to the warehouses and tools your team uses.
Every data team that builds Amazon integrations learns the same painful lesson: raw API data is nearly useless for analysis. Orders show one set of fees. Settlements show another. Financial events use codes that don't match either. The same product has three different identifiers depending on which endpoint you query via the Selling Partner API.
Normalized Amazon data solves this chaos. It transforms Amazon's messy outputs into a clean, consistent data model where every metric means the same thing across all your reports and dashboards. This is essential for accurate P&L analytics.
What Does "Normalized" Amazon Data Actually Mean?
Data normalization is the process of organizing data to reduce redundancy and improve consistency. According to IBM's data normalization guide, this typically involves structuring tables to eliminate data anomalies. For Amazon seller data specifically, normalization involves:
Unified Identifiers
ASIN, SKU, FNSKU, and Merchant SKU all mapped to a single product entity. No more joining on five different keys to find the same product.
Consistent Fee Mapping
Amazon's 200+ fee types consolidated into logical categories. "FBAPerUnitFulfillmentFee" and "FBAFulfillmentFee" become one thing for your product feed.
Standardized Schemas
Date formats, currency codes, and numeric precision all follow the same conventions across every table and report.
Pre-Calculated Metrics
Contribution margin, TACoS, and return rates calculated once, correctly. No more spreadsheet formulas that break.
The Amazon Data Chaos Problem
To understand why normalization matters, you need to see what raw Amazon data actually looks like. Here's a sample of the inconsistencies you'll encounter when working with Seller Central reports:
The Identifier Nightmare
A single product can have 5+ identifiers across Amazon's systems:
ASIN: B08XYZ1234 (Amazon's catalog identifier)
Seller SKU: WIDGET-BLU-LG (your internal code)
FNSKU: X001ABC123 (FBA inventory label)
Merchant SKU: SKU-12345 (legacy identifier)
MSKU: Sometimes same as Seller SKU, sometimes not
Different reports use different identifiers. Orders use SKU. Inventory uses FNSKU. Settlements use ASIN. Advertising uses both. Without normalization, joining this data requires complex, error-prone logic.
Data Source
Fee Field Name
What It Actually Means
Orders API
ItemPrice.Amount
Revenue before fees
Settlement Report
product-sales
Revenue after promotions
Financial Events
ProductCharges
Revenue after all adjustments
Financial Events
FBAPerUnitFulfillmentFee
Pick and pack fee
Fee Preview API
FulfillmentFee
Pick and pack fee (same thing, different name)
This is just a glimpse. Amazon has 200+ distinct fee types, date fields that sometimes include timezone and sometimes don't, and amounts that are sometimes strings and sometimes numbers. Building reports on raw data is an exercise in frustration. Our guide on why Amazon numbers don't match dives deeper into this problem.
What a Normalized Amazon Data Model Looks Like
A properly normalized data model transforms chaos into clarity. Here's an example of how key entities get structured, following Kimball dimensional modeling best practices:
Example: Normalized Product Table
CREATE TABLE products (
  product_id          UUID PRIMARY KEY, asin                VARCHAR(10), seller_sku          VARCHAR(50), fnsku               VARCHAR(15), title               TEXT, brand               VARCHAR(100), category            VARCHAR(100), size_tier           VARCHAR(20), -- 'standard' or 'oversize'
  marketplace_id      VARCHAR(20), status              VARCHAR(20), -- 'active', 'inactive', 'stranded'
  created_at          TIMESTAMP WITH TIME ZONE, updated_at          TIMESTAMP WITH TIME ZONE
);

-- Every other table references product_id, not ASIN/SKU/FNSKU
-- Joins become trivial: orders.product_id = products.product_id
With this structure, calculating P&L becomes a simple query instead of a complex reconciliation project. This is what powers Nova's winners and losers analysis:
-- P&L by product: simple, fast, accurate
SELECT
  p.seller_sku, p.title, SUM(of.net_revenue) as revenue, SUM(of.total_fees) as amazon_fees, SUM(of.gross_profit) as gross_profit, AVG(of.margin_percent) as avg_margin
FROM order_financials of
JOIN products p ON of.product_id = p.product_id
WHERE of.order_date BETWEEN '2024-01-01' AND '2024-12-31'
GROUP BY p.seller_sku, p.title
ORDER BY gross_profit DESC;
Fee Normalization: The 200+ Fee Type Problem
Amazon charges over 200 distinct fee types. Many are variations of the same thing. Others appear under different names in different reports. Normalization maps these into a manageable taxonomy that you can use for FBA fee reduction strategies:
Inbound shipping, removals, disposal, liquidation, various adjustments...
150+
Pro Tip: Why Fee Normalization Matters for P&L
Without fee normalization, your P&L statement is always wrong. A "FBAPerUnitFulfillmentFee" in February might become "FBAPickPackFee" in March when Amazon updates their systems. Your year-over-year comparisons break. Normalized data uses consistent categories regardless of what Amazon calls things internally.
Multi-Marketplace Normalization
Selling on multiple Amazon marketplaces multiplies the complexity. Each marketplace has different fee structures, currencies, and even field names. See our multi-marketplace analytics guide for deeper coverage:
Challenge
Raw Data Problem
Normalized Solution
Currency
USD, GBP, EUR, JPY all mixed together
Convert to base currency with daily rates from ECB
Timezones
Some reports UTC, some local, some unlabeled
All timestamps normalized to UTC
Fee Names
UK uses "FulfilmentFee", US uses "FulfillmentFee"
Single canonical name across all regions
Product Matching
Same product has different ASINs per marketplace
Global product entity with regional variants
For global sellers, normalization is non-negotiable. Without it, comparing UK and US performance requires manual spreadsheet work every time.
Benefits of Normalized Amazon Data
Faster Analysis
Queries that took hours of data prep now run in seconds. Your team spends time on insights, not data wrangling. Power your custom analytics.
Trustworthy Numbers
When everyone uses the same normalized dataset, debates about "whose numbers are right" disappear. Critical for executive reporting.
Easier Integrations
Combine Amazon data with Shopify, marketing spend, or warehouse systems. Normalized data plays well with Tableau and other BI tools.
Future-Proof
When Amazon changes their API schemas (quarterly), normalized data insulates you from breaking changes. Read about SP-API rate limits.
Need Clean Amazon Data in Your Warehouse?
Stop wrestling with raw SP-API data. Our team can show you how Nova delivers pre-normalized, query-ready Amazon data directly to Snowflake, BigQuery, or Redshift.
You have three paths to normalized Amazon data. Each involves trade-offs:
Option 1: Build It Yourself
Write ETL code that extracts from SP-API, transforms data, and loads to your warehouse.
Pros:
Full control over data model
No vendor dependency
Custom transformations
Cons:
12-18 months to build
$300K+ engineering cost
Ongoing maintenance forever
Option 2: ETL Tool + dbt Models
Use Fivetran or Airbyte for extraction, then build dbt models for normalization.
Pros:
Faster than DIY (3-6 months)
Uses existing tools
Community dbt packages available
Cons:
Still need data modeling expertise
ETL + warehouse + dbt costs add up
Amazon-specific complexity remains
Option 3: Data-as-a-Service Provider
Use a provider like Nova that delivers pre-normalized Amazon data to your warehouse. Learn more in our Amazon DaaS guide.
Pros:
Live in days, not months
900+ metrics
Zero maintenance burden
Cons:
Monthly cost
Less control over exact schema
Vendor dependency
For most teams, option 3 is the fastest path to value. You can always build custom layers on top of normalized data. But starting with clean data accelerates everything else. Nova's on-demand data delivery can get you started in days.